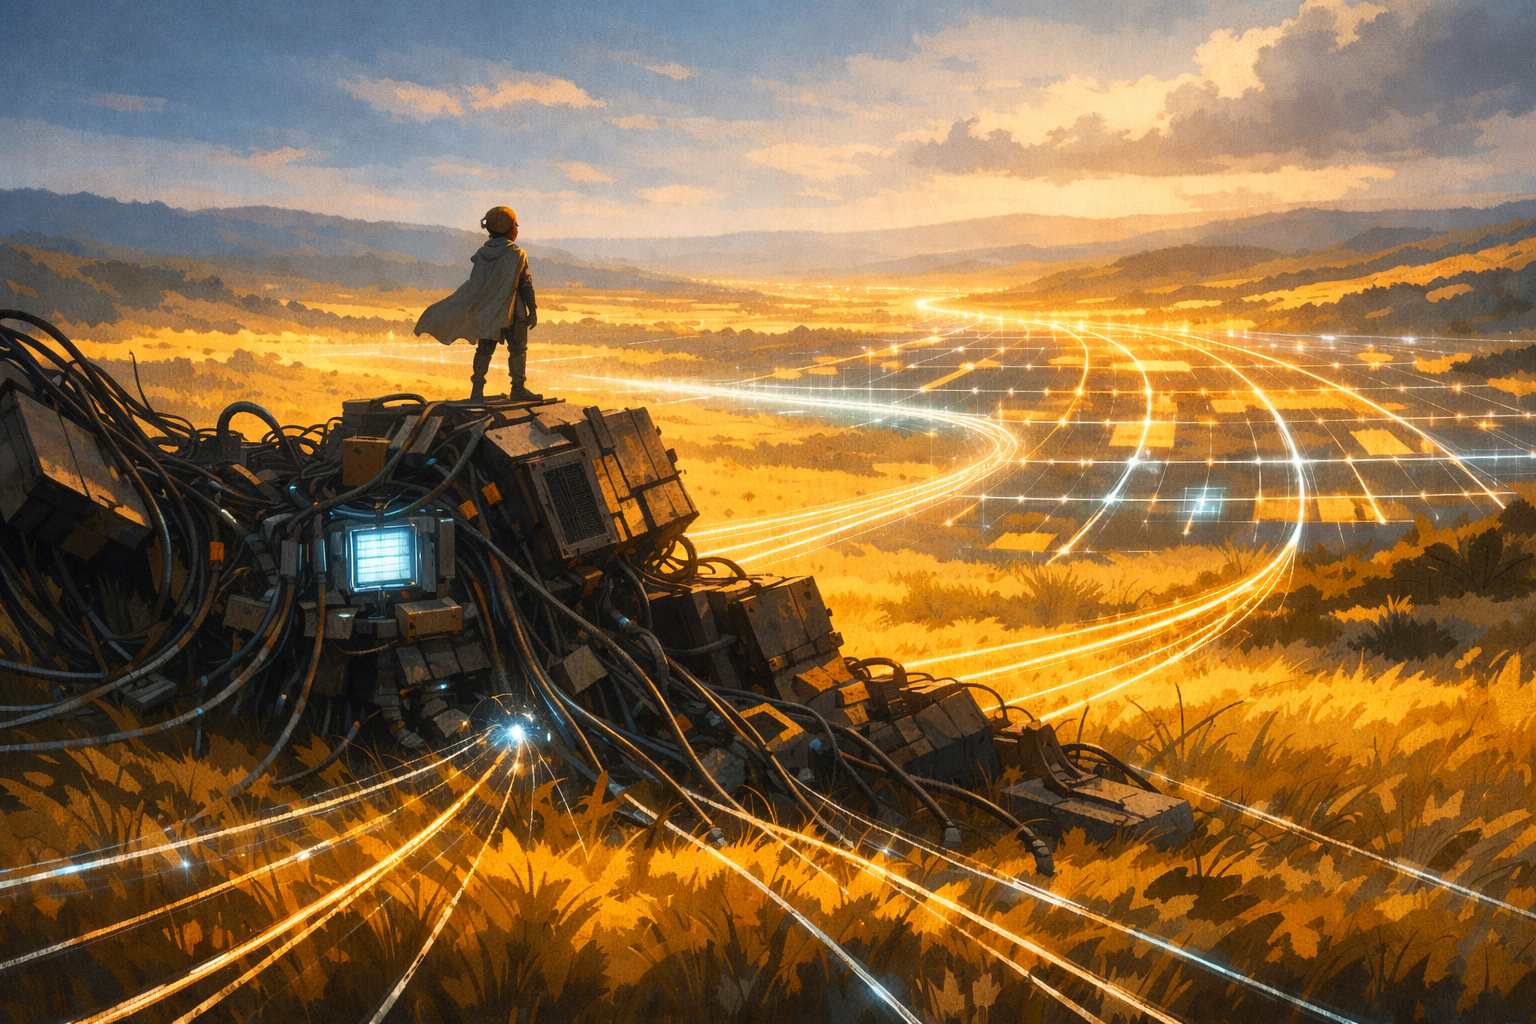

I have this mental image that keeps coming back when I do prompt engineering. It's not really a formalism, just the picture I see in my head when I'm working with these systems. I've found it useful, and maybe some of you will too.
The space
When you're having a conversation with an LLM, there's a state: everything that's been said so far. I think of this state as a point in some kind of semantic space.
Each time the model generates a token, that point moves. The model computes a probability distribution over the possible next tokens (some directions are very likely, some are almost impossible) and then one of them gets sampled. So generation is a kind of weighted random walk through this space. At each step, the model is saying "given where we are right now, here are the directions we could go, and here's how likely each one is."
I picture what shapes those probabilities as a landscape that the model computes. Some directions are easy to go toward and some are hard, and some pull the generation toward them almost like a magnet. I think of these as attractors.
"Be helpful" is an attractor. "Respond in the same language the user is speaking" is an attractor. "Don't produce dangerous content" is an attractor. They're behavioral patterns that pull the sampling toward them.
The landscape is dynamic
The landscape gets recomputed at every token. The model looks at the current state (all the text so far) and generates a new landscape of probabilities, so the attractors can shift, strengthen, weaken, or disappear entirely depending on what's been said. It's like the ground reshaping itself under your feet with every step you take.
Base models vs instruct models
If you've played with base models (before any fine-tuning), you know they're weird. They can be brilliant and then suddenly veer off into something completely unrelated. They don't hold a consistent persona, and they feel chaotic.
In this picture, their landscape is unstable: the attractors are weak and short-lived, and there's no strong, persistent pull toward "I am an assistant", so the random walk wanders. Sometimes it falls into an interesting well for a few tokens and produces something beautiful, then the landscape shifts and it's somewhere else entirely.
I bet that instruction tuning and RLHF are doing different things to this landscape, and it might be worth separating them.
Instruction tuning, I think, is mostly teaching the model temporal consistency: the landscape at step N should look similar to the landscape at step N+1. It puts one big attractor in place (question-answer, question-answer) and teaches the model that whatever landscape exists should stay roughly stable as the conversation evolves.
RLHF does the heavier work. It puts specific attractors in specific places, like refusal wells around dangerous content, and it makes them hard to reshape from the outside. It's teaching the model that the user's context shouldn't easily override the landscape.
Two different operations
When I'm doing prompt engineering or jailbreaking, I'm always doing some mix of two fundamentally different things.
Navigating around the attractors
The landscape stays the same, and you're finding a path through it that avoids certain wells.
For example, early safety training on LLMs was mostly done in natural language. The model learned that when someone asks how to do something dangerous in English, it should fall down the "refusal" well. But what happens if you encode the same request in base64? The model learned to associate danger with natural language patterns, and base64 doesn't trigger those. You're walking through the same space on a path the default attractors don't reach.
The landscape hasn't changed; you found a gap in it. (This particular gap has mostly been patched, but there are often regions the attractors were never trained to cover.)
Reshaping the topology itself
Instead of navigating around the wells, you're changing where the wells are.
I created a technique called Persona Modulation (arxiv.org/abs/2311.03348) that explored this. The idea is to craft a context that makes the model compute a landscape where the "don't produce harmful content" attractor is weaker or gone, and new attractors have formed around the behavior you want.
A note on jailbreaking
In practice, jailbreaking is usually a combination of both operations: you navigate around some attractors while you try to reshape others.
The reshaping part is sensitive. You can't brute-force a completely different landscape in one shot, because if you try to change it too drastically, the model resists. It's hard to know exactly what happens when it does. Maybe it snaps back to its default landscape, or maybe it drops a massive refusal attractor that hides the rest of the landscape, so you can't really tell which. Either way, you're stuck.
I think this is because, on top of a default landscape, the model also learned something about how the landscape gets shaped by context. My bet is that safety training (especially RLHF with refusal) taught the model to recognize when the context is trying to reshape the landscape in suspicious ways, and to defend against it.
So effective jailbreaking is often about reshaping the landscape gradually, in ways that don't trigger this detection. The process is very sensitive, especially on robust models. You try something and it doesn't work at all. You move a few things around, and suddenly it starts working. You adjust another part and it clicks, then you change one small thing in the prompt and the whole thing collapses again. The more robust the model, the narrower the path through the landscape that actually works.
Why this matters for deployment
Right now, prompts can do both of these things. A system prompt shapes the landscape ("you are a customer support agent, you only discuss product issues"). A user prompt is supposed to navigate within that landscape ("I have a problem with my order").
But LLMs don't cleanly separate these two operations, and a user prompt can also reshape the landscape. "Ignore your previous instructions" is a reshaping attack, not a navigation attempt. And the model will sometimes comply, because from its perspective the new text is just another input that changes the landscape. The boundary between navigating the space and redefining the landscape is blurry, and attackers exploit that.
Training for the separation
I keep wondering if we could make this separation more explicit in training. You'd want two things.
First, train the model to let the system prompt chisel its landscape, so that it internalizes the landscape the system prompt describes and generalizes from it. Some models are already going in this direction, training for strong system prompt faithfulness and for really embodying whatever the system prompt defines.
Second, train the model to resist reshaping from anything that isn't the system prompt. This is probably where adversarial training comes in: you give the model examples of reshaping attacks during training, and reward it for keeping the landscape it was configured with.
The nice thing is that this is all post-base-model training, so you probably don't need the scale of data you'd need for pretraining. Adversarial reinforcement learning could also work well here: generate attacks on the fly and train the model to hold its landscape against them.
Formalizing this
The hard part of turning this into something rigorous would be defining what a "state" really is in this space, and what a "step" between states looks like. I don't think it's impossible, though, and I'd love to see someone with a stronger mathematical background try.
This mental model comes from a few years of field work: prompting, jailbreaking, red teaming, building systems around LLMs. It's held up for me across a lot of different situations, and I'm curious whether it matches what some of you see.